Why AI Developers Are Buying Up Physical Books to Clean Up the Web
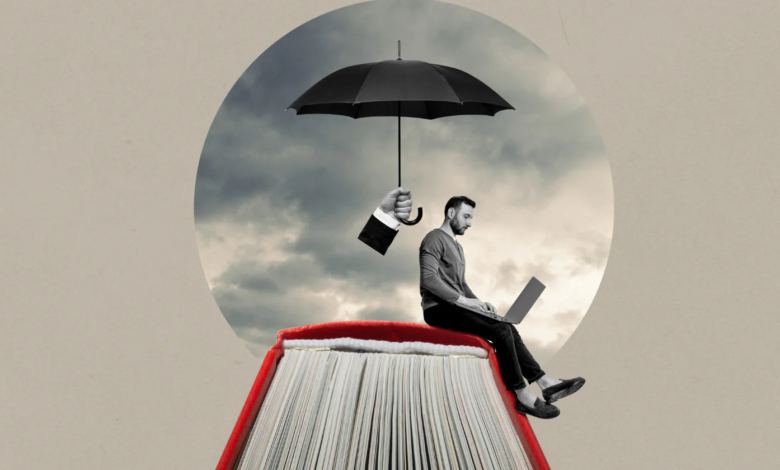
In an unexpected turn for the digital era, major artificial intelligence developers are purchasing warehouse pallets filled with traditional paper books. Brokers such as ISBNdb, which facilitate bulk print sales to tech laboratories, openly advertise that the highest-quality training material for machine learning remains on physical library shelves. The reasoning is simple: books published prior to the recent flood of automated web content offer clean, human-written text that remains untainted by synthetic output.
This dynamic creates a striking contradiction across the tech ecosystem. While frontier laboratories spend substantial sums on physical literature to prevent their systems from training on automated material, a growing sector of software vendors charges monthly fees to help businesses flood the internet with machine-generated articles.
The Breakdown of Traditional Metrics in Generative Search
For decades, digital marketing relied on deterministic tracking. Search engine rankings corresponded to specific positions, generating predictable impressions and clicks that could be monitored through analytics parameters all the way to conversion. While attribution models were frequently debated, the fundamental measurement pipeline remained stable.
Generative responses do not offer that stability. Submitting the exact same query multiple times to an interactive model can yield entirely different brand mentions and structural answers. Although underlying probability distributions dictate these outputs, the tools used to monitor them rely primarily on automated API calls. These synthetic probes query systems in isolation, stripping away the personal context, location details, and browsing history that shape what human users actually see. Consequently, tracking tools often deliver precise metrics regarding synthetic interactions that do not reflect real-world user experiences.
Rather than addressing these structural limitations, many analytics platforms have introduced dashboards promising “position tracking” and “share of voice” reports for fluid generative interfaces. At the same time, many of these same software vendors market mass-content generation tools designed to target systems whose creators are actively building mechanisms to filter out automated writing.
Escalating Watermarking and Detection Infrastructure
Technological measures to identify synthetic media are expanding rapidly at the infrastructure level. At Google I/O, details emerged regarding SynthID, an invisible watermarking technology that has already tagged more than 100 billion synthetic images and videos alongside roughly 60,000 years of audio content. This identification framework is integrated directly into Google Search and Chrome. Meanwhile, OpenAI has committed to applying SynthID watermarks across all images produced via ChatGPT, Codex, and its developer API. Additional industry partners adopting these identification standards include Kakao, ElevenLabs, and NVIDIA through its Cosmos models.
While some content creators argue that text generation remains difficult to track compared to visual or audio media, recent regulatory and technical updates are altering that reality:
- Open-Source Text Reference Limits: DeepMind’s open-source SynthID repository explicitly notes that its publicly inspectable text-watermarking code serves only as a research reference and lacks production-grade cryptographic guarantees. The internal detection methods deployed by major search infrastructure remain undisclosed.
- EU AI Act Requirements: Article 50 of the European Union’s AI Act mandates that creators of generative AI systems mark synthetic outputs—including text—in a machine-readable format. This rule applies from August 2, with a pending AI Omnibus package potentially extending compliance deadlines to December for existing market offerings. Notably, the regulation includes a carve-out for public interest text where a human assumes explicit editorial responsibility.
- Model-Level Integration: Anthropic signed the EU AI Act Code of Practice and implemented system-level text watermarking for Claude models deployed from August 2, 2026, onwards. Applied across APIs, consumer applications, and cloud environments globally, these embedded markers track text directly at the model output stage.
In response to these tracking efforts, various evasion utilities have appeared online, attempting to remove watermarks from platforms like Claude, Gemini, and ChatGPT through automated paraphrasing. However, because proprietary detection algorithms are kept confidential by search and safety engineering teams, third-party stripping tools cannot verify whether their modifications successfully remove invisible signals.
Why Low-Quality AI Content Fails Quality Standards
Even if technical watermarks were entirely bypassed through paraphrasing or multi-model translation, high-volume automated publishing faces fundamental quality hurdles.
A useful historical parallel exists in the manufacturing of scientific instruments after 1945. Because atmospheric nuclear testing contaminated newly forged steel with background radiation, instrument makers salvaged clean, pre-war steel from sunken shipwrecks. Today, text written before 2022 functions as the digital equivalent of that pre-war steel. AI development laboratories are acquiring massive collections of printed books specifically because pre-2022 literature requires no filtering against synthetic feedback loops.
Mass-produced web content that simply repackages existing online text struggles to provide original insights, making it vulnerable to automated web quality filters regardless of whether explicit watermarks are present.
How Parametric Memory Shapes AI Behavior
Understanding how generative models process information reveals why high-volume publishing offers diminishing returns. Research indicates that a system’s internal training memory heavily influences its downstream behavior before it ever executes a live web search.
In a study published in late July by AI visibility platform geoSurge, researchers evaluated model actions across nine distinct industries using 66 buyer-focused prompts and nearly 4,000 generated responses. The findings revealed a clear pattern:
- Brands recorded within a model’s top-10 internal memory for a category were included in subsequent search queries at 3.2 times the rate of unremembered brands (55.7% compared to 17.4%).
- When a model’s search query included a specific brand name, 63% of the time it selected a brand from its top-five internal recall.
- The data suggests that when generative systems initiate web queries, they predominantly seek out entities they have already encoded into memory during training.
Independent academic research supports this emphasis on internal knowledge encoding. In a study presented at ICML, Google Research evaluated 13 language models across more than 4 million graded responses. The researchers found that while frontier models successfully encoded 95% to 98% of tested factual information into their parameters, they failed to directly recall 25% to 33% of those facts without explicit contextual priming. The recall gap between widely documented facts and obscure information exceeded 20 percentage points, even though the underlying encoding gap was only 5 points.
These findings highlight a core reality of machine learning: basic factual encoding is relatively common, but reliable, unprompted recall requires broad, consistent representation across foundational training data. Simply generating large volumes of repetitive web pages fails to establish the deep parametric memory necessary for consistent representation in generated answers.
The Misalignment Between Marketing Tools and Training Lifecycles
A fundamental disconnect exists between the billing models of software vendors and the operational reality of artificial intelligence models:
- Reporting Timelines vs. Model Updates: Analytics subscriptions operate on monthly or quarterly cycles, but foundational parametric memory is built during lengthy training runs that occur over months or years.
- Short-Term Metrics: To align with quarterly reporting, vendors emphasize immediate metrics like automated mention counts and output volume.
- Depreciation Risks: When training filters are updated or search systems refine their quality algorithms, mass-generated content can lose indexing or visibility without warning, even as subscription costs remain fixed.
As frontier laboratories continue purchasing physical print archives to maintain clean training pipelines, the long-term value of mass-produced web text continues to decline. Marketers and developers navigating this landscape must weigh the temporary metrics of automated generation against the lasting requirements of true algorithmic authority.